CSAT can be a useful metric, but only when the team is clear about what the customer is actually rating. The moment behind the score matters more than the neatness of the dashboard. In practice, CSAT tends to work when it stays close to one interaction, one fresh memory, and one team that can actually do something with the answer.
CSAT looks simple, and that is usually where the sloppiness starts
It is easy to set up.
One short question. Quick response. Easy to trend. Compared with bigger feedback programs, it feels lightweight and manageable. That is part of the appeal.
It is also why teams get loose with it.
A lot of weak CSAT programs are not broken because the question is bad. They are weak because nobody stays disciplined about what the customer is meant to be rating. The survey goes out, the scores come back, and only later does the team realize they were never fully aligned on the moment behind the answer.
That creates a very familiar kind of confusion.
If the moment is fuzzy, the score is fuzzy
There is no real way around that.
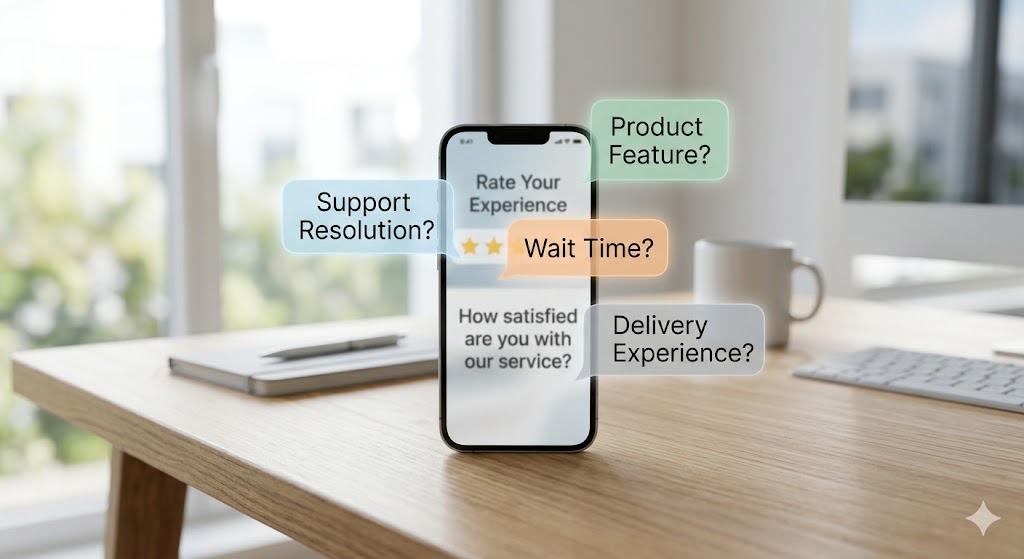
What exactly is the customer responding to?
- the support resolution itself?
- the wait before the resolution?
- the handoff between teams?
- the delivery experience?
- frustration that started earlier and only surfaced now?
- a blended impression of the last few interactions?
Once the answer turns into “probably some mix of those,” the metric has already started to lose usefulness.
You can still report on it. You can still compare trends. But the team will spend too much time debating what the number really refers to.
This is what shows up in actual reviews
A lower score comes in.
Support says the ticket was handled correctly. Operations says the delay happened earlier. Product thinks the frustration started before the customer ever contacted support. None of them is necessarily wrong.
The problem is that the measurement is doing too many things at once.
That is why vague CSAT becomes annoying so quickly. It creates visibility, but not much clarity. The number exists. The action path does not.
Narrower usually works better
This sounds less ambitious, which may be why teams resist it.
Still, tighter scope is what makes CSAT more usable.
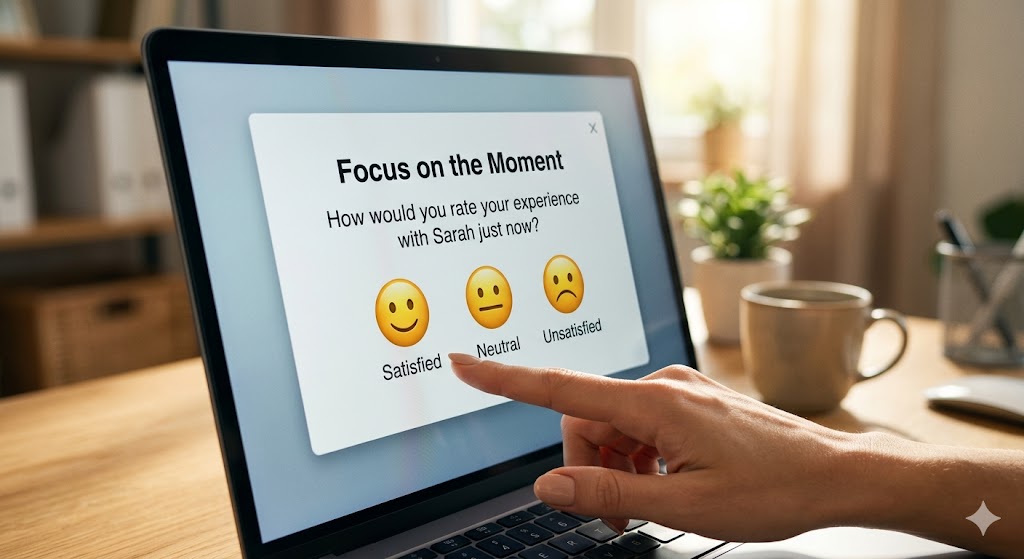
A resolved support conversation is a decent example. So is a delivery event. A setup step. An onboarding checkpoint. Something the customer can reasonably hold in mind as one thing, even if the experience around it was not perfect.
Once that is true, the score gets easier to trust.
So do the comments. You are no longer trying to figure out whether “frustrating” refers to this interaction, the one before it, or the whole string of events the customer has bundled together.
A quick test
Before putting too much weight on a CSAT flow, it helps to ask:
- Can we name the exact moment being measured?
- Is the customer likely to remember that moment clearly enough?
- Can one team act on the answer without a long interpretive debate?
If those answers are weak, the setup is probably weak too.
Context helps, but it should not have to rescue the metric
A good CSAT setup still needs context.
If a support score is poor, it helps to know whether the customer had to repeat themselves. If a delivery score slips, you want to know whether the problem was delay, damage, or communication. If a user gives poor feedback after onboarding, it matters whether they got stuck once or kept hitting the same step.
But there is a difference between context making the answer more useful and context having to save a vague measurement.
Teams blur that line all the time.
The better version is not complicated: ask about one real moment, then keep just enough surrounding information with the answer that someone can act on it without too much guesswork.
The mistakes are usually the usual ones
Most broken CSAT setups drift into one or two familiar problems:
- the survey goes out after too much has already happened
- the team wants transactional feedback, but the answer picks up broader frustration
- the score is tracked, but nobody is clear on the follow-up path
- the shortness of the question gets mistaken for precision
That last one is especially common.
A short question does not make a measurement moment well defined.
If a tool like Insightto.ai helps tie the response back to the workflow, page, or interaction around it, that is useful enough. Not because it makes CSAT sound more strategic than it is. Just because it cuts down the guessing after the answer shows up.
One practical rule is probably enough here:
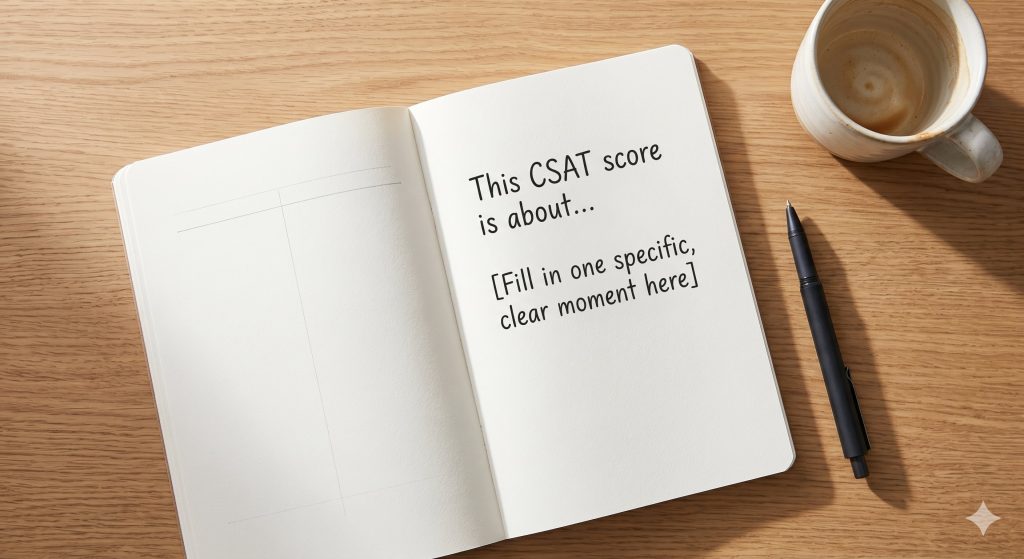
If you cannot finish the sentence “This CSAT score is about…” without immediately qualifying it, the setup likely needs work.